In July 2025, a team at UC San Diego published Serving LLMs in HPC Clusters: A Comparative Study of Qualcomm Cloud AI 100 Ultra and NVIDIA Data Center GPUs (Sada et al.; I’m reading v3, October 2025). A year later, Qualcomm completed its acquisition of Modular, the company behind the MAX inference framework and the Mojo language. A month after that, Modular showed MAX running on the same Qualcomm accelerator.
Those three events raise a question the paper had no way to ask: how much better does this chip get with a newer software stack? This post explains what the paper found, why its numbers suggest there’s more to get from the hardware, and how I plan to measure it. The first results post covers how I built and validated the benchmark harness.
Why inference, and why now
Training a model is a one-time cost. Serving it is paid on every request, for as long as the model is in use, and for most organizations running LLMs that’s now where most of the compute and the power bill goes. At that point the numbers that matter are tokens per joule and how finely you can divide hardware among users, not peak FLOPS. Accelerators built for inference, like Qualcomm’s Cloud AI 100, are designed around exactly those two numbers. The question is whether the software lets them deliver.
The paper in one paragraph
The authors serve 12 open models, from GPT-2 (124M parameters) to three 70B models, on two kinds of hardware in the National Research Platform (NRP), a shared Kubernetes cluster used by more than 300 research groups. One side is a node with 8 Qualcomm Cloud AI 100 Ultra cards at the San Diego Supercomputer Center. Each card contains four independent chips (“devices”). The other side is nodes with 4 or 8 NVIDIA A100 80 GB GPUs. Both sides serve through vLLM: stock vLLM on the A100s, and a Qualcomm-provided vLLM fork on Cloud AI 100 (SDK 1.20), where each model is first exported to ONNX and compiled ahead of time into a Qualcomm Program Container (QPC). The benchmark sweeps output length (10 to 2,048 tokens) × concurrent requests (1 to 32), and it measures throughput and accelerator power.
What the paper found
In the authors’ words, Qualcomm “achieves competitive energy efficiency with advantages on specific models while enabling more granular hardware allocation.” Their examples make the granularity point concrete:
- Small models on a quarter of a card. granite-3.2-8b serves from a single Cloud AI 100 device at 36 W, where the A100 setup used four GPUs at 1,246 W.
- A 70B model on one card. Nemotron-70B runs on one card (four devices) at 148 W, where the A100 setup used eight GPUs at 2,983 W.
For a shared cluster serving hundreds of groups, being able to hand out a 36 W slice instead of a whole 80 GB GPU is an operational advantage in its own right.
The paper is also clear that A100s deliver higher absolute throughput, and it frames Qualcomm’s case around power budgets and granularity. Plotting both halves of its Table 2 (200 output tokens, 4 parallel requests) shows where Qualcomm already leads:
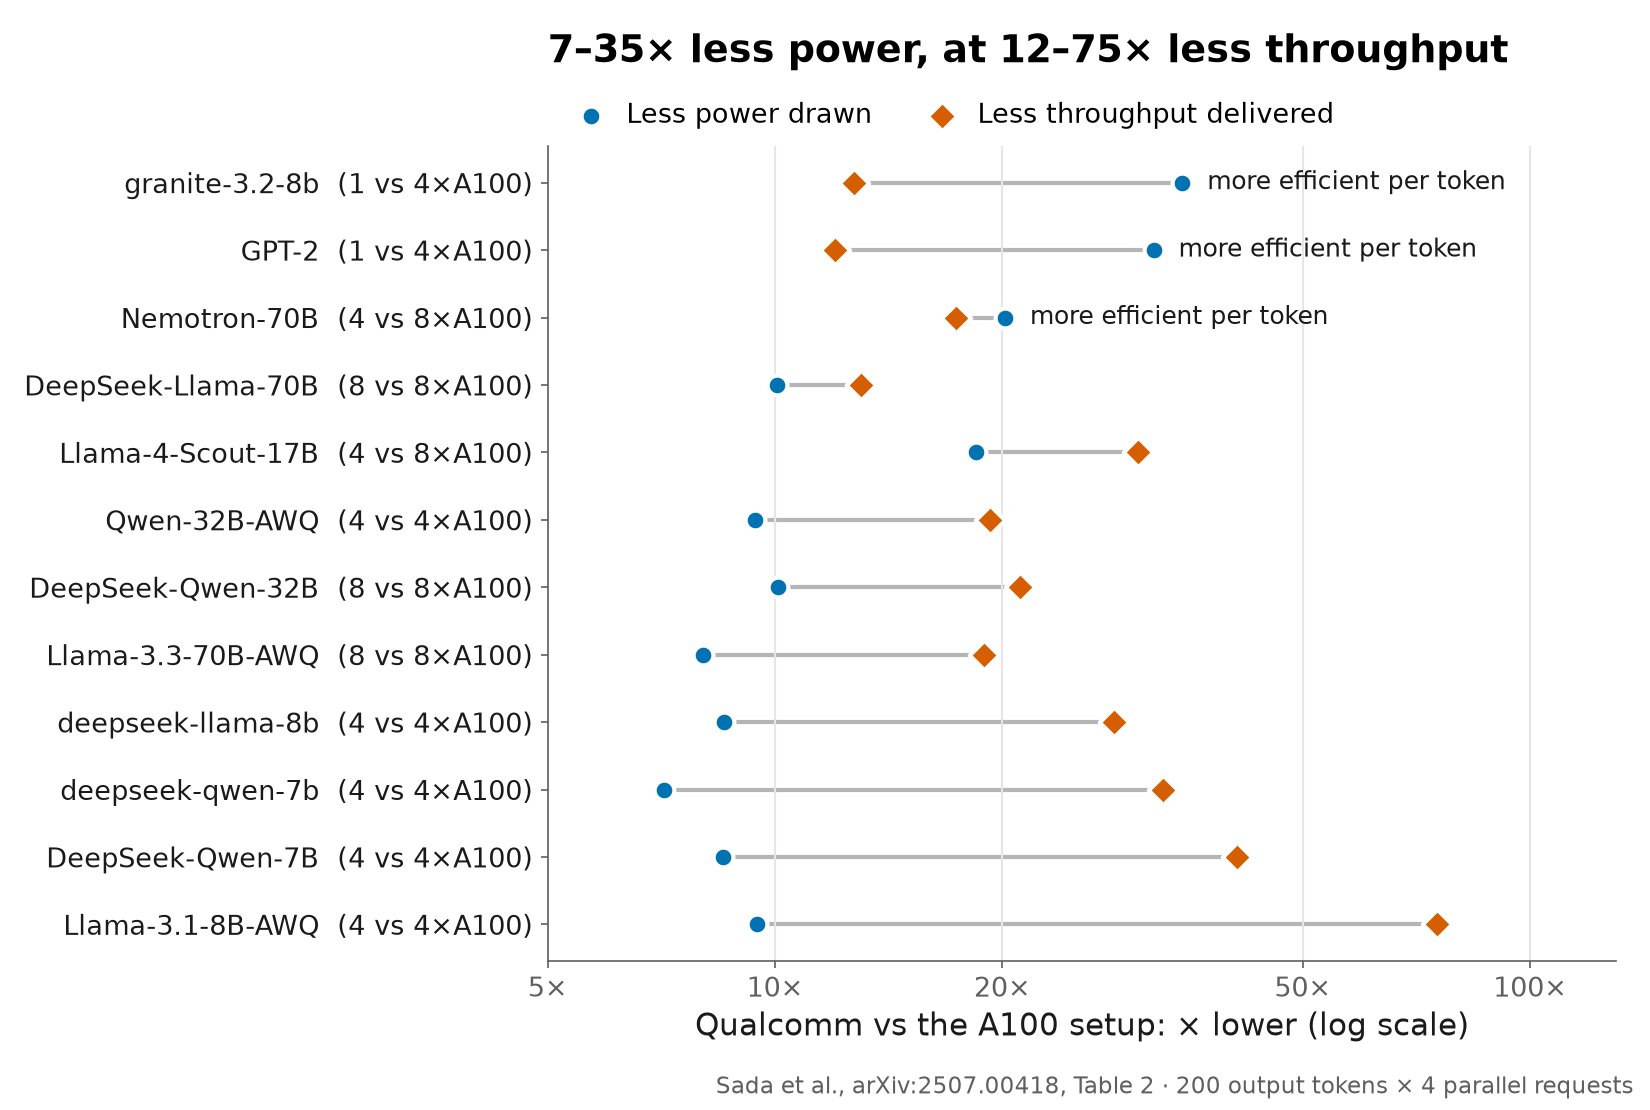
Where the power saving (blue) is larger than the throughput gap (orange), Qualcomm produces more tokens per joule. Dividing one by the other gives the efficiency ratio, which the paper reports in its Table 3:
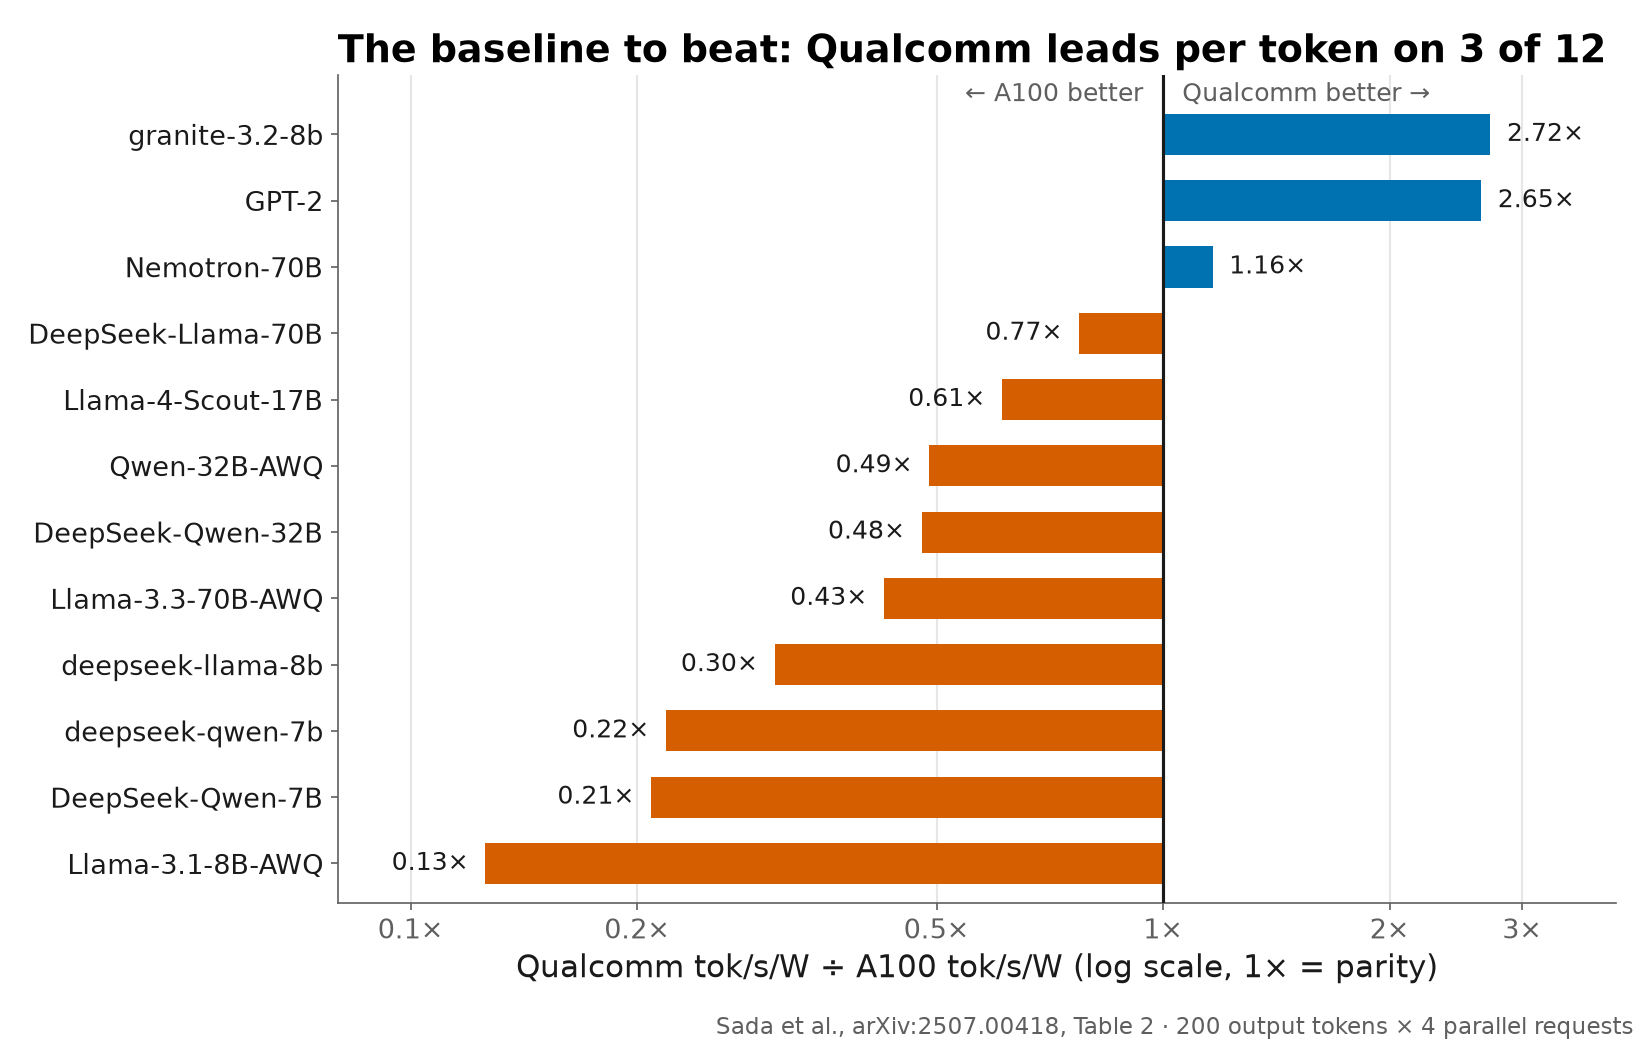
These are the “specific models” in the abstract: granite-3.2-8b (2.7×), GPT-2 (2.7×), and Nemotron-70B (1.16×), on 2025 software. This chart is the baseline I want to move. If a new stack raises Qualcomm’s throughput without raising its power much, bars move right, and the count of models above parity goes up.
The headroom is in the software
The most interesting numbers in the paper are the ones that don’t line up, because they point at what software could fix. Two pairs of models stand out:
| Pair | Qualcomm devices | Throughput | Power |
|---|---|---|---|
| granite-3.2-8b | 1 | 25 tok/s | 36 W |
| DeepSeek-R1-Distill-Llama-8B (same size) | 4 | 24 tok/s | 140 W |
| DeepSeek-R1-Distill-Llama-70B | 8 | 8 tok/s | 292 W |
| Nemotron-70B (same Llama-70B architecture) | 4 | 6 tok/s | 148 W |
In both pairs, similar models get similar throughput from very different amounts of silicon. If the chip’s raw capability set the limit, four devices would do more than one. Something between the model and the silicon is doing the limiting: how the model is exported, compiled, split across devices, and scheduled.
Two more signs point the same way:
- Batching is fixed at compile time. Each Qualcomm model is compiled ahead of time for a batch size of 1, 2, or 4, and the paper notes that “compilation can take hours.” To compare like with like, the authors capped vLLM on the A100 to the same batch size. So neither side batched more than four requests, even in the 16- and 32-request tests. Batching many requests together is the main way servers turn spare compute into throughput.
- Per-user speed is low. Most models serve at 6–25 tok/s across four concurrent requests, a few tokens per second for each user. GPT-2, which is small enough to be compute-light, reaches 218 tok/s on a single device. The hardware can clearly move faster than most of these numbers show.
The paper doesn’t say which precision each Qualcomm model was compiled at (FP16 or INT8) or which batch size, and those may explain part of the gaps above. But precision and batch size are software choices too. Every step in the path is software: the ONNX export, the ahead-of-time compile, the device partitioning, and a vLLM fork maintained separately from upstream vLLM.
I can’t tell from outside how much of the gap software can close. That’s what the re-run is for.
Why MAX is the stack to test
On July 29, 2026, Qualcomm completed its acquisition of Modular and said that “Mojo, MAX, and Modular Cloud will continue as products and brands.” Modular’s pitch has always been portability without a performance penalty: one serving stack (MAX), one kernel language (Mojo), many kinds of hardware. At ModCon in August, the Modular team wrote that “the same code that runs on NVIDIA and AMD GPUs can now target Qualcomm Technologies’ silicon.” They showed GPT-2 reaching “6.7× the baseline” after about three weeks of optimization, and Gemma 4 31B served across a card’s four devices with tensor parallelism.
That 6.7× is measured against a PyTorch implementation on Cloud AI 100, not against the paper’s vLLM setup, so the two can’t be put side by side yet. This paper is the natural yardstick to close that gap:
- It’s the best public “before” picture. It’s an independent, published measurement of Qualcomm’s inference stack before MAX, with power, on the accelerator Modular now targets. If MAX unlocks the hardware, it shows up here as more throughput at similar watts.
- Its protocol is concrete enough to reproduce. The paper spells out the test grid, the client (Python
requestsplus a thread pool), how throughput is computed, and how power is sampled. That makes a re-run with a different software stack a like-for-like comparison, not a new benchmark. - The batch limit has a measurable answer. If MAX can serve Cloud AI 100 at 16 or 32 concurrent requests without a fixed-batch compile, that changes what the chip is good for.
- Portability has to hold on both sides. Running MAX on the A100 against vLLM checks that a portable stack doesn’t cost performance on NVIDIA hardware. Running MAX on Qualcomm checks that it helps the new hardware.
- “Same code” is testable. Writing one Mojo kernel and running it unchanged on an Apple GPU, an NVIDIA GPU, and, with luck, a Qualcomm device is the most direct check of the portability claim I can do from outside.
The experiment
I keep everything the paper specifies, run it on both engines, and set up both sides as well as each can be set up:
| Paper | This re-run | |
|---|---|---|
| Test grid, client, throughput formula | 6 lengths × 5 concurrency, requests + thread pool | Same |
| Engines | vLLM on both sides | vLLM and MAX on A100; MAX on Qualcomm |
| Batch cap | Both capped at the QPC batch (1, 2, or 4) | Both: a paper-faithful capped run and each system at its best |
| Hardware per model | Qualcomm 1–8 devices; A100 4 or 8 GPUs | The fewest that fit on each side (1 A100 for ≤8B models), plus the paper’s setup for a few models so the numbers line up |
| Precision | A100 fp16; Qualcomm fp16 or INT8 | bf16 on every engine, stated per row (MAX offers bf16, not fp16, for most models) |
| Power | 1 s sampling, accelerator only | 1 s sampling plus NVML’s energy counter, windows of ≥5 s, idle measured |
| Latency | End-to-end | Also time to first token and inter-token latency, measured warm |
| Reporting | The 200-token × 4-request cell | All 30 cells, prompts, code, and raw data on GitHub |
Right-sizing works in both directions. Fewer A100s for small models will likely improve the A100’s tokens per watt, and lifting the batch cap should help both chips. I’ll report both effects.
The hypotheses, stated before the runs
Each one comes with what would count as failure.
- H1, Qualcomm: MAX serves the paper’s models on Cloud AI 100 Ultra at substantially higher throughput than the paper’s numbers, at similar power, so more models land above parity. This fails if the throughput stays in the same range.
- H2, A100: MAX matches or beats vLLM in throughput and tok/s/W on the same GPU. This fails if MAX is slower or less efficient in most cells.
- H3, right-sized A100: serving ≤8B models on 1 A100 instead of 4 raises the A100’s tokens per watt, so the fair comparison on those models is closer than Table 2 shows. This fails if the A100’s efficiency doesn’t improve.
- H4, Mojo: one Mojo kernel runs unchanged on Apple, NVIDIA, and Qualcomm silicon. This fails if it needs per-chip rewrites.
I’ll report every result with the same prominence, whichever way it goes. An independent number is only useful if it could have come out the other way, and that matters more now that Qualcomm owns both the chip and the software stack. The biggest risk is H1: I don’t yet have access to Qualcomm hardware. If that doesn’t change, H1 will be reported as unanswered, and H2–H4 will still stand on their own.
What’s next
The harness is built and validated. The pilot post covers the three measurement problems it caught on a MacBook before any GPU money was spent. Next come A100 runs, vLLM against MAX, and the search for Qualcomm access.
The figures in this post come from the paper’s Table 2, transcribed to
results/paper/sada2025-table2.csv
and plotted by analysis/plot_paper.py.
Updated September 29, 2026: reframed around what a new software stack could add, and corrected how I described the paper’s findings. An earlier version attributed the “10–35×” power figure to the abstract; it comes from the conclusion, and the abstract describes efficiency as competitive, with advantages on specific models.